Five APIs.
One unified platform.
Parse, extract, redact, match, and query your documents. RESTful APIs, hosted on an ethical cloud in Switzerland. Every answer returns the page it came from.
Platform tokens are currently provisioned by our team. We'll get you set up within a business day.
# Your first Roylon API call: document intelligence in a few lines
import requests

with open("contract.pdf", "rb") as f:
    response = requests.post(
        "https://api.roylon.ai/v1/parse",
        headers={"Authorization": "Bearer ryl_plat_..."},
        files={"file": f},
    )

doc = response.json()
print(f"Parsed {doc['page_count']} pages in {doc['timings']['parse_ms']} ms")Roylon Parse
Convert PDFs, Office files, HTML, and images into clean, chunked content with real page numbers and bounding boxes. Smart OCR skips text-based pages automatically. Subprocess-isolated so one bad document can't take the service down.
- 25+ formats: PDF, DOCX, XLSX, PPTX, HTML, Markdown, images
- Real page numbers & bounding boxes on every chunk
- Smart OCR skips already-extractable pages to speed up parsing
- Table-aware chunking with header repetition
- Multilingual: 80+ languages auto-detected
- PDF-First pipeline for accurate coordinates on non-PDFs
import requests

with open("contract.pdf", "rb") as f:
    resp = requests.post(
        "https://api.roylon.ai/v1/parse-and-chunk",
        headers={"Authorization": "Bearer ryl_plat_demo_..."},
        files={"file": f},
        data={"chunk_max_tokens": 512},
    )

doc = resp.json()
print(f"{doc['page_count']} pages, {len(doc['chunks'])} chunks")
for chunk in doc["chunks"][:3]:
    print(f"  p.{chunk['page']}: {chunk['text'][:80]}...")
import { readFile } from "node:fs/promises";
const file = await readFile("contract.pdf");
const form = new FormData();
form.set("file", new Blob([file]), "contract.pdf");
form.set("chunk_max_tokens", "512");
const resp = await fetch("https://api.roylon.ai/v1/parse-and-chunk", {
method: "POST",
headers: { Authorization: "Bearer ryl_plat_demo_..." },
body: form,
});
const doc = await resp.json();
console.log(`${doc.page_count} pages, ${doc.chunks.length} chunks`);curl -X POST https://api.roylon.ai/v1/parse-and-chunk \
-H "Authorization: Bearer ryl_plat_demo_..." \
-F "file=@contract.pdf" \
-F "chunk_max_tokens=512"
# Response:
# {
# "page_count": 12,
# "language": "en",
# "chunks": [
# { "page": 1, "bbox": [72, 80, 540, 120], "text": "..." },
# ...
# ]
# }
Roylon Extract
Turn invoices, receipts, and contracts into strongly-typed JSON with a confidence score on every field and the source text each field came from. Low-confidence fields route to human review automatically.
- Pre-built schemas: invoice, receipt, contract
- Per-field confidence scoring (0.0–1.0)
- Source grounding: every field mapped to its origin text
- Cross-field validation with auto-retry (totals, sums)
- Human-in-the-loop review for low-confidence fields
- Batch processing: 100+ documents async
import requests

with open("invoice.pdf", "rb") as f:
    resp = requests.post(
        "https://api.roylon.ai/v1/extract",
        headers={"Authorization": "Bearer ryl_plat_demo_..."},
        files={"file": f},
        data={"schema_id": "extraction.invoice"},
    )

result = resp.json()
print(f"Vendor: {result['vendor_name']['value']}")
print(f"  confidence: {result['vendor_name']['confidence']:.2%}")
print(f"Total: {result['total_amount']['value']} {result['currency']}")

# Flag low-confidence fields for review
for field, data in result.items():
    if isinstance(data, dict) and data.get("confidence", 1) < 0.8:
        print(f"  ⚠ review: {field}")
import { readFile } from "node:fs/promises";
const file = await readFile("invoice.pdf");
const form = new FormData();
form.set("file", new Blob([file]), "invoice.pdf");
form.set("schema_id", "extraction.invoice");
const resp = await fetch("https://api.roylon.ai/v1/extract", {
method: "POST",
headers: { Authorization: "Bearer ryl_plat_demo_..." },
body: form,
});
const result = await resp.json();
console.log(`Vendor: ${result.vendor_name.value}`);
console.log(`Total: ${result.total_amount.value} ${result.currency}`);curl -X POST https://api.roylon.ai/v1/extract \
-H "Authorization: Bearer ryl_plat_demo_..." \
-F "file=@invoice.pdf" \
-F "schema_id=extraction.invoice"
# Response includes per-field confidence + source grounding:
# {
# "vendor_name": { "value": "Acme Corp", "confidence": 0.98 },
# "total_amount": { "value": 1620.00, "confidence": 0.99 },
# "line_items": [...],
# "review_status": null
# }
Roylon Redact
Detect sensitive data and replace it with encrypted tokens. Authorised roles can decrypt originals under audit; everyone else sees the redacted version. Built for teams who need GDPR and nFADP compliance without losing the ability to work with the underlying data.
- Reversible tokens, not permanent redaction
- Role-based clearance (full/partial/redacted/public)
- Named entity detection across 8 languages
- Per-tenant vault encryption (envelope keys)
- Full audit trail on every detokenization
- GPU-optional: fast on CPU, accelerated on GPU
import requests

resp = requests.post(
    "https://api.roylon.ai/v1/pii/tokenize",
    headers={
        "Authorization": "Bearer ryl_plat_demo_...",
        "Content-Type": "application/json",
    },
    json={
        "text": "John Smith (john@acme.com) filed on 2024-01-15",
        "entity_types": ["PERSON", "EMAIL", "DATE"],
    },
)

data = resp.json()
print(data["tokenized_text"])
# "<<PII:PERSON:a1b2>> (<<PII:EMAIL:c3d4>>) filed on <<PII:DATE:e5f6>>"

print(data["embedding_labels"])
# "[Person Name] ([Email Address]) filed on [Date]"
const resp = await fetch("https://api.roylon.ai/v1/pii/tokenize", {
method: "POST",
headers: {
Authorization: "Bearer ryl_plat_demo_...",
"Content-Type": "application/json",
},
body: JSON.stringify({
text: "John Smith (john@acme.com) filed on 2024-01-15",
entity_types: ["PERSON", "EMAIL", "DATE"],
}),
});
const data = await resp.json();
console.log(data.tokenized_text);
// <<PII:PERSON:a1b2>> (<<PII:EMAIL:c3d4>>) filed on <<PII:DATE:e5f6>>curl -X POST https://api.roylon.ai/v1/pii/tokenize \
-H "Authorization: Bearer ryl_plat_demo_..." \
-H "Content-Type: application/json" \
-d '{
"text": "John Smith (john@acme.com) filed on 2024-01-15",
"entity_types": ["PERSON", "EMAIL", "DATE"]
}'
# Response:
# {
# "tokenized_text": "<<PII:PERSON:a1b2>> (<<PII:EMAIL:c3d4>>) filed on...",
# "embedding_labels": "[Person Name] ([Email Address]) filed on [Date]",
# "entities": [...]
# }Roylon Match
Index candidates, products, or proposals with custom schemas, then surface the best matches by meaning and by the rules you set. Bidirectional: works equally well for job → candidate and candidate → job flows. Every score comes with a breakdown.
- Custom schemas: you decide which fields are compared
- Matches filtered, compared by meaning and weighted by your rules
- Bidirectional matching (source ↔ target)
- Upsert on change: never re-embed unchanged records
- Explainability: score breakdowns on demand
- Indexed fields for fast rule-based filtering
import requests

resp = requests.post(
    "https://api.roylon.ai/v1/platform/match/collections/candidates/search",
    headers={
        "Authorization": "Bearer ryl_plat_demo_...",
        "Content-Type": "application/json",
    },
    json={
        "query": {
            "title": "Senior Python Engineer",
            "description": "5+ years, AWS expertise",
        },
        "filters": [
            {"field": "location", "op": "in",
             "value": ["Remote", "San Francisco"]},
        ],
        "modifiers": [
            {"type": "boost", "field": "status", "op": "eq",
             "value": "active", "weight": 0.1},
        ],
        "top_k": 10,
        "explain": True,
    },
)

for match in resp.json()["results"]:
    print(f"{match['score']:.2f}  {match['payload']['title']}")
const resp = await fetch(
"https://api.roylon.ai/v1/platform/match/collections/candidates/search",
{
method: "POST",
headers: {
Authorization: "Bearer ryl_plat_demo_...",
"Content-Type": "application/json",
},
body: JSON.stringify({
query: {
title: "Senior Python Engineer",
description: "5+ years, AWS expertise",
},
filters: [
{ field: "location", op: "in", value: ["Remote", "SF"] },
],
top_k: 10,
explain: true,
}),
}
);
const { results } = await resp.json();
results.forEach((r) => console.log(r.score, r.payload.title));curl -X POST \
https://api.roylon.ai/v1/platform/match/collections/candidates/search \
-H "Authorization: Bearer ryl_plat_demo_..." \
-H "Content-Type: application/json" \
-d '{
"query": {"title": "Senior Python Engineer"},
"filters": [
{"field": "location", "op": "in", "value": ["Remote"]}
],
"top_k": 10,
"explain": true
}'
# Response:
# { "results": [
# { "score": 0.94, "external_id": "c-123", "payload": {...},
# "breakdown": { "semantic": 0.87, "boost": 0.07 } }
# ]
# }Roylon Agents
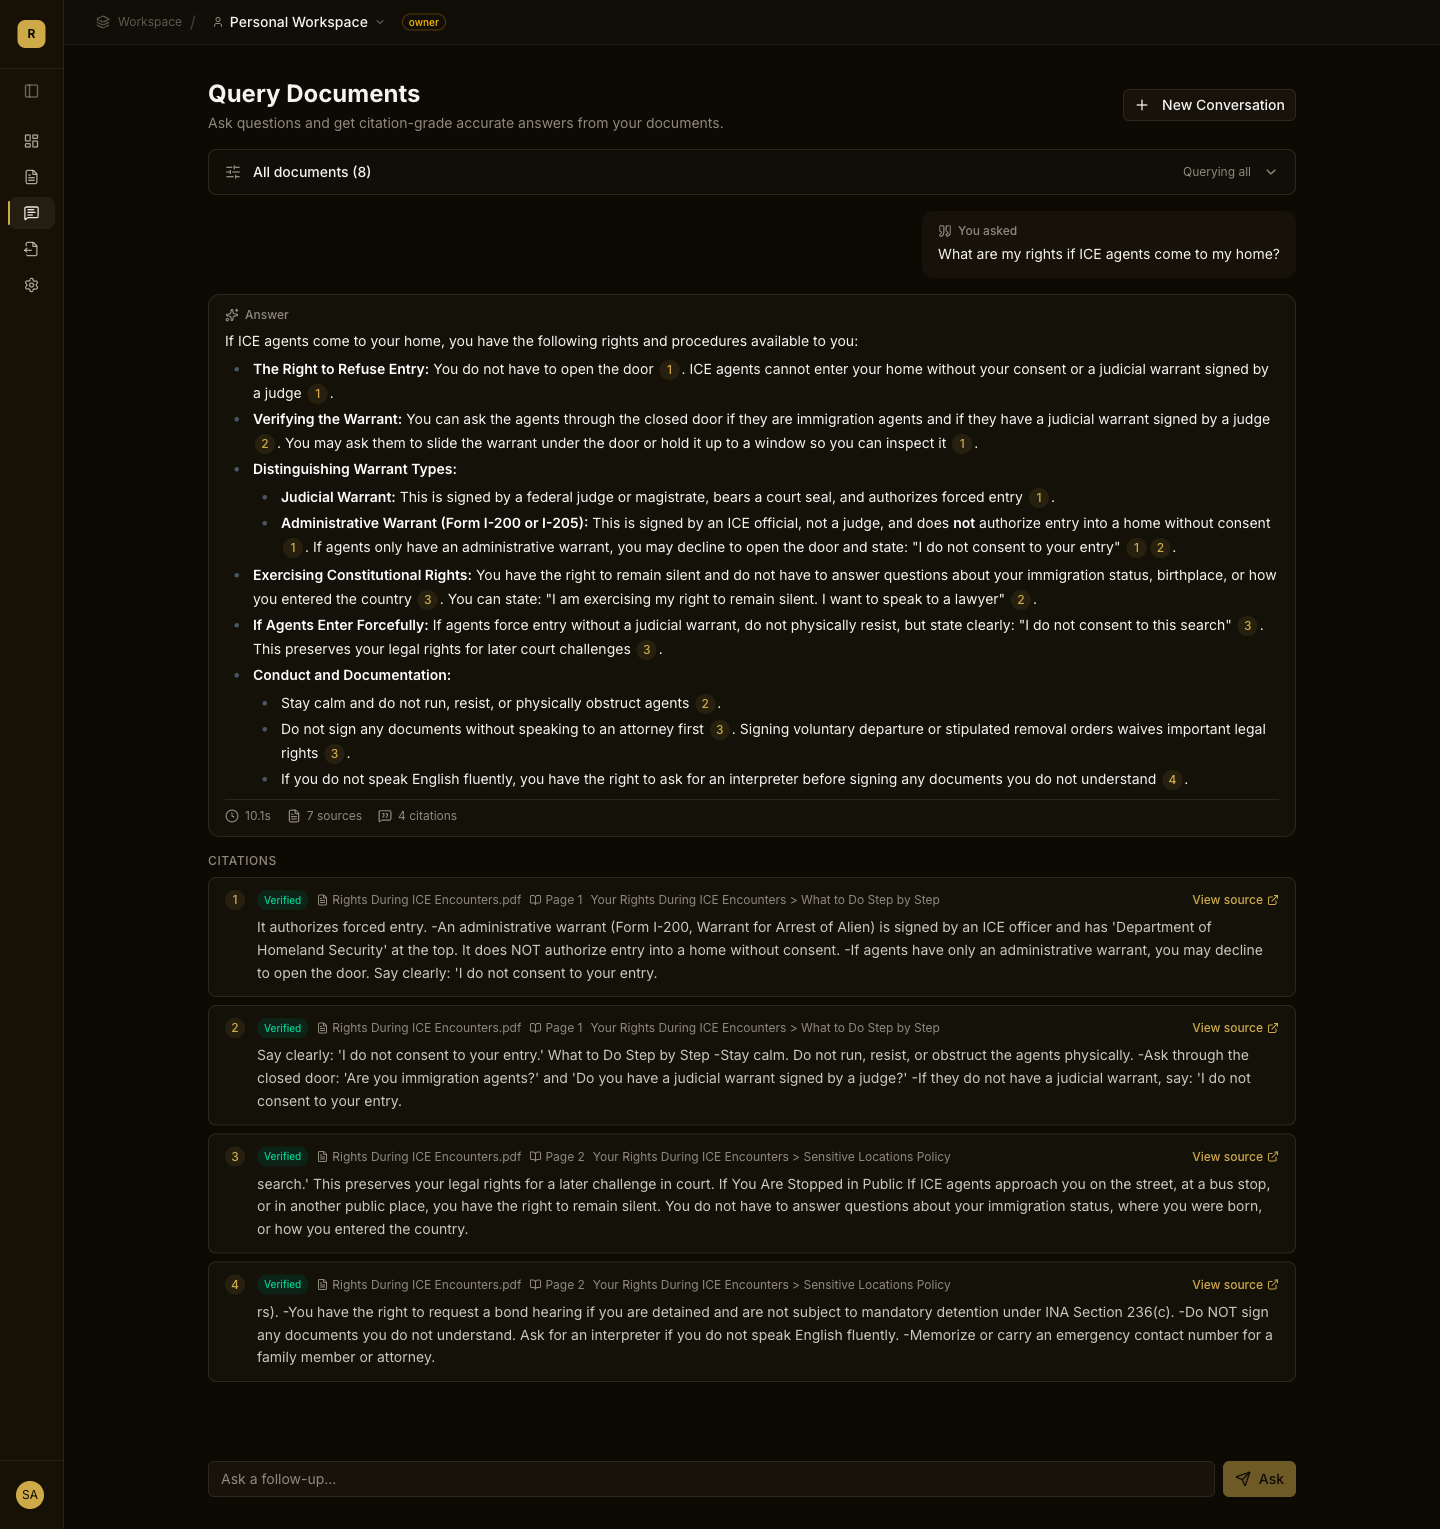
The Q&A engine behind console.roylon.ai. Every answer is grounded in retrieved passages and verified before it reaches the user, so citations point at the exact page and paragraph. Streaming, multi-turn, multilingual.
- Citation verification: every answer is checked against the passage it cites
- Understands what a question asks for: a search, a follow-up or a translation
- Multi-turn conversations with server-side history
- Streaming responses: token events plus citation overlay
- Multilingual: translate answers to target language
- Search by keyword and by meaning, with the best matches first
import requests

resp = requests.post(
    "https://api.roylon.ai/v1/query",
    headers={
        "Authorization": "Bearer ryl_plat_demo_...",
        "Content-Type": "application/json",
    },
    json={
        "question": "What are the termination clauses?",
        "workspace_id": "ws_legal_...",
        "target_language": "en",
    },
)

answer = resp.json()
print(answer["answer"])

# Every claim is backed by a verified citation
for cite in answer["citations"]:
    print(f"  [{cite['document_name']} p.{cite['page']}]")
const resp = await fetch("https://api.roylon.ai/v1/query", {
method: "POST",
headers: {
Authorization: "Bearer ryl_plat_demo_...",
"Content-Type": "application/json",
},
body: JSON.stringify({
question: "What are the termination clauses?",
workspace_id: "ws_legal_...",
target_language: "en",
}),
});
const answer = await resp.json();
console.log(answer.answer);
// Citations verified against the source passage
answer.citations.forEach((c) =>
console.log(` [${c.document_name} p.${c.page}]`)
);curl -X POST https://api.roylon.ai/v1/query \
-H "Authorization: Bearer ryl_plat_demo_..." \
-H "Content-Type: application/json" \
-d '{
"question": "What are the termination clauses?",
"workspace_id": "ws_legal_...",
"target_language": "en"
}'
# Response:
# {
# "answer": "Either party may terminate with 30 days...",
# "citations": [
# { "document_name": "contract.pdf", "page": 12,
# "bbox": [72, 420, 540, 480], "source": "Section 8.2" }
# ],
# "conversation_id": "conv_..."
# }
Under every endpoint
Platform capabilities.
The infrastructure enterprises expect. Hosted in Switzerland on an ethical cloud. Built for regulated trust.
API Tokens & Auth
Platform tokens (ryl_plat_*) with fine-grained scopes. Optional CIDR allowlists. Instant revocation.
Plan-aware Rate Limits
10/min (free) up to 2000/min (enterprise). Burst capacity + fair metering across every endpoint.
Audit Trail
Every API call logged with full traceability. User, workspace, latency, outcome. Exportable for compliance teams.
Multi-tenant by design
Every resource scoped by tenant. Per-tenant encryption. Complete data isolation.
Ethical cloud hosting
Geneva and Winterthur data centres. ISO 27001 infrastructure. Independent Swiss provider, 100% renewable energy.
Privacy-first by default
GDPR + nFADP compliant. Swiss law applies to your data. Never used to train AI models.
Quickstart
Ship in an afternoon
- 1
Request access
Platform tokens are provisioned by our team, typically within one business day.
Contact Sales - 2
Make your first call
Authenticate with
See code samplesAuthorization: Bearerand start sending requests. Python, Node.js, and cURL examples are ready above. - 3
Compose the platform
Each API is independent, but they compose. Parse → Redact → Agents for regulated RAG. Parse → Extract for structured pipelines.
See use cases
Build on an ethical cloud.
Swiss-hosted on ISO 27001-certified infrastructure. Never used to train anyone's model.